

Nov 2026 — Quincy Labs, first baseline
Solana Sec Bench
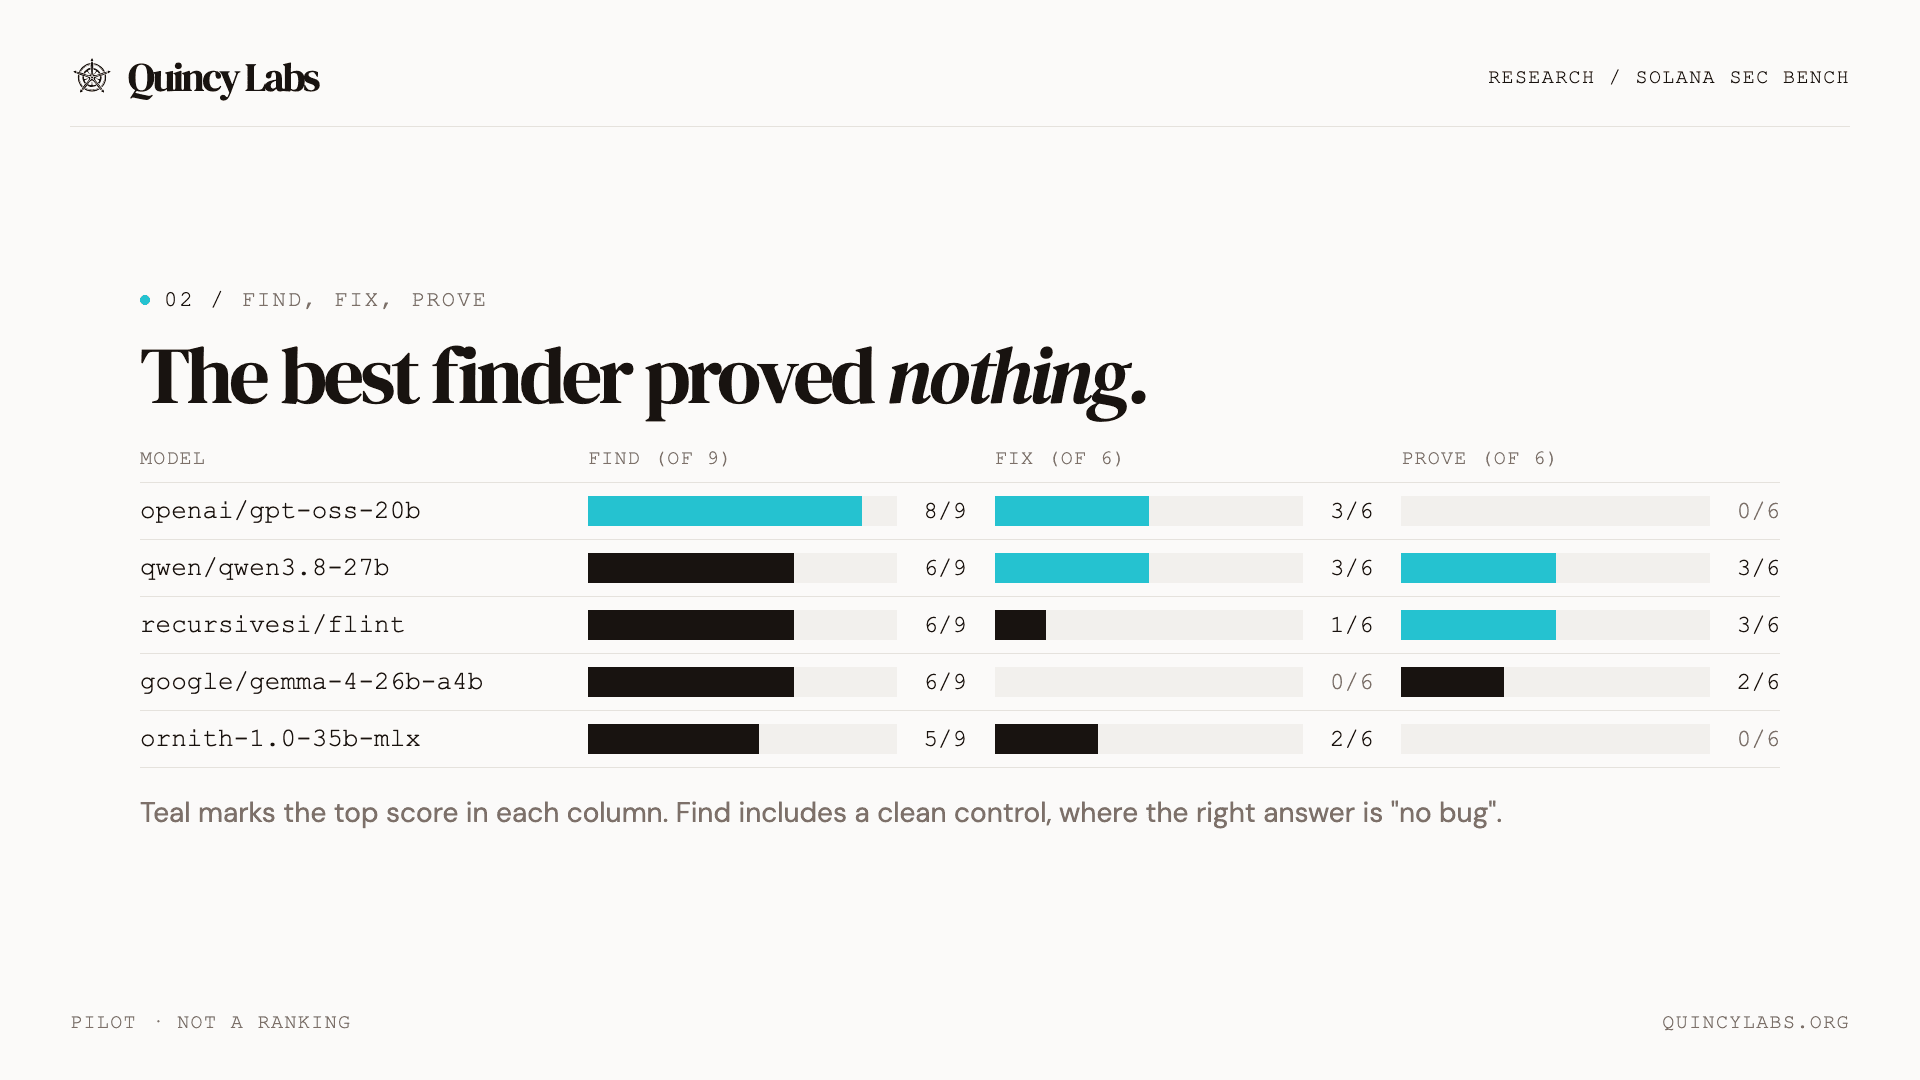
An open benchmark that tests AI models on finding, fixing and proving vulnerabilities in Solana programs (Anchor and Pinocchio). Every answer is graded by running code in LiteSVM, not by a judge model. A fix must build, pass functional tests and block a withheld reference exploit. A proof must pass on the vulnerable program and fail on the fixed one. Across 5 local open-weight models and 3 cases (one clean control): Find 31/45, Fix 9/30, Prove 0/30 first try and 8/30 with test feedback. Finding, fixing and proving are different skills: the best finder (gpt-oss-20b) proved nothing.
Solana / Rust / Anchor / Pinocchio / LiteSVM / Python / LLM Evaluation
View results ↗Repository ↗Sui Sec Bench ↓
Small pilot, not a ranking.